Preprint · 2026
Learning to Factorize and Adapt: A Versatile Approach Toward Universal Spatio-Temporal Foundation Models
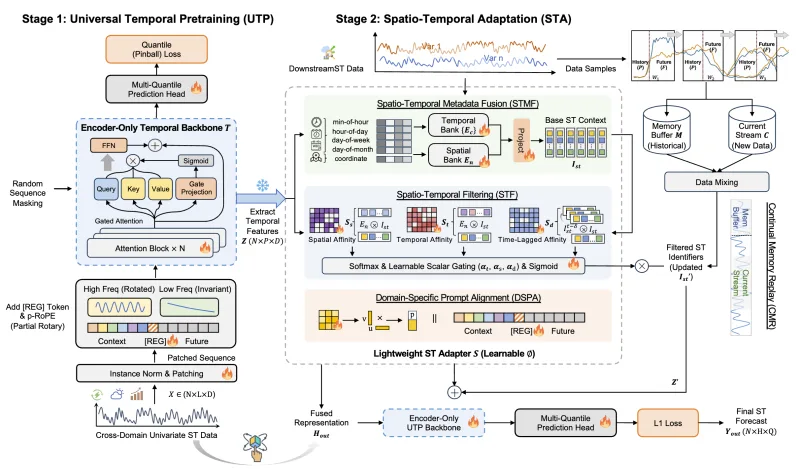
A unified temporal backbone for variable-length context and probabilistic forecasting, with full pretrained weight reuse during downstream adaptation.
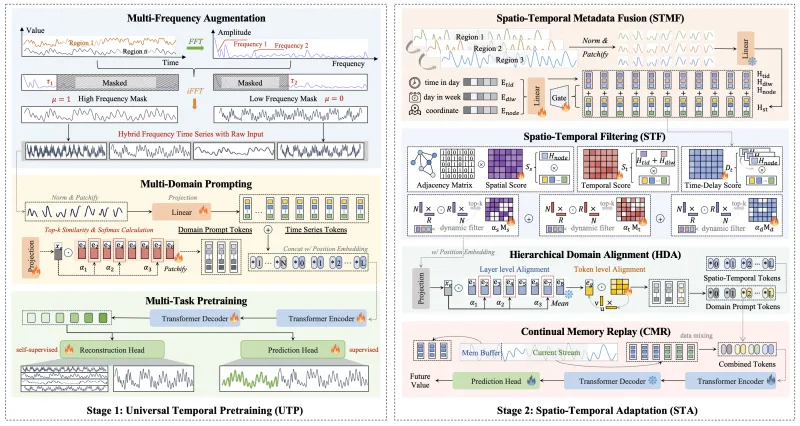
I designed Universal Temporal Pretraining (UTP) and ran its pretraining, cross-domain evaluation, and ablation studies.
Method & evaluation
The encoder-only quantile model uses normalized sequence patches and randomly masked history prefixes, with gated attention and partial rotary positional encoding. It was configured for up to 2,048 input steps and 256 forecast steps; fixed-weight zero-shot evaluations used 12→12 and 96→96 context/forecast settings on benchmarks excluded from pretraining.
On PEMS08 at 96→96, the model with history masking achieved an MAE of 91.09 versus 107.22 without masking, a 15% relative reduction. See Tables IX–X in the paper.